Public learning pages
Landing, about, grammar case, and preview routes introduce structured language learning content.
Case study
A multilingual vocabulary platform linking public lessons and protected study workflows to progress tracking, cultural-text ingestion, image generation, and AI-assisted vocabulary pipelines.
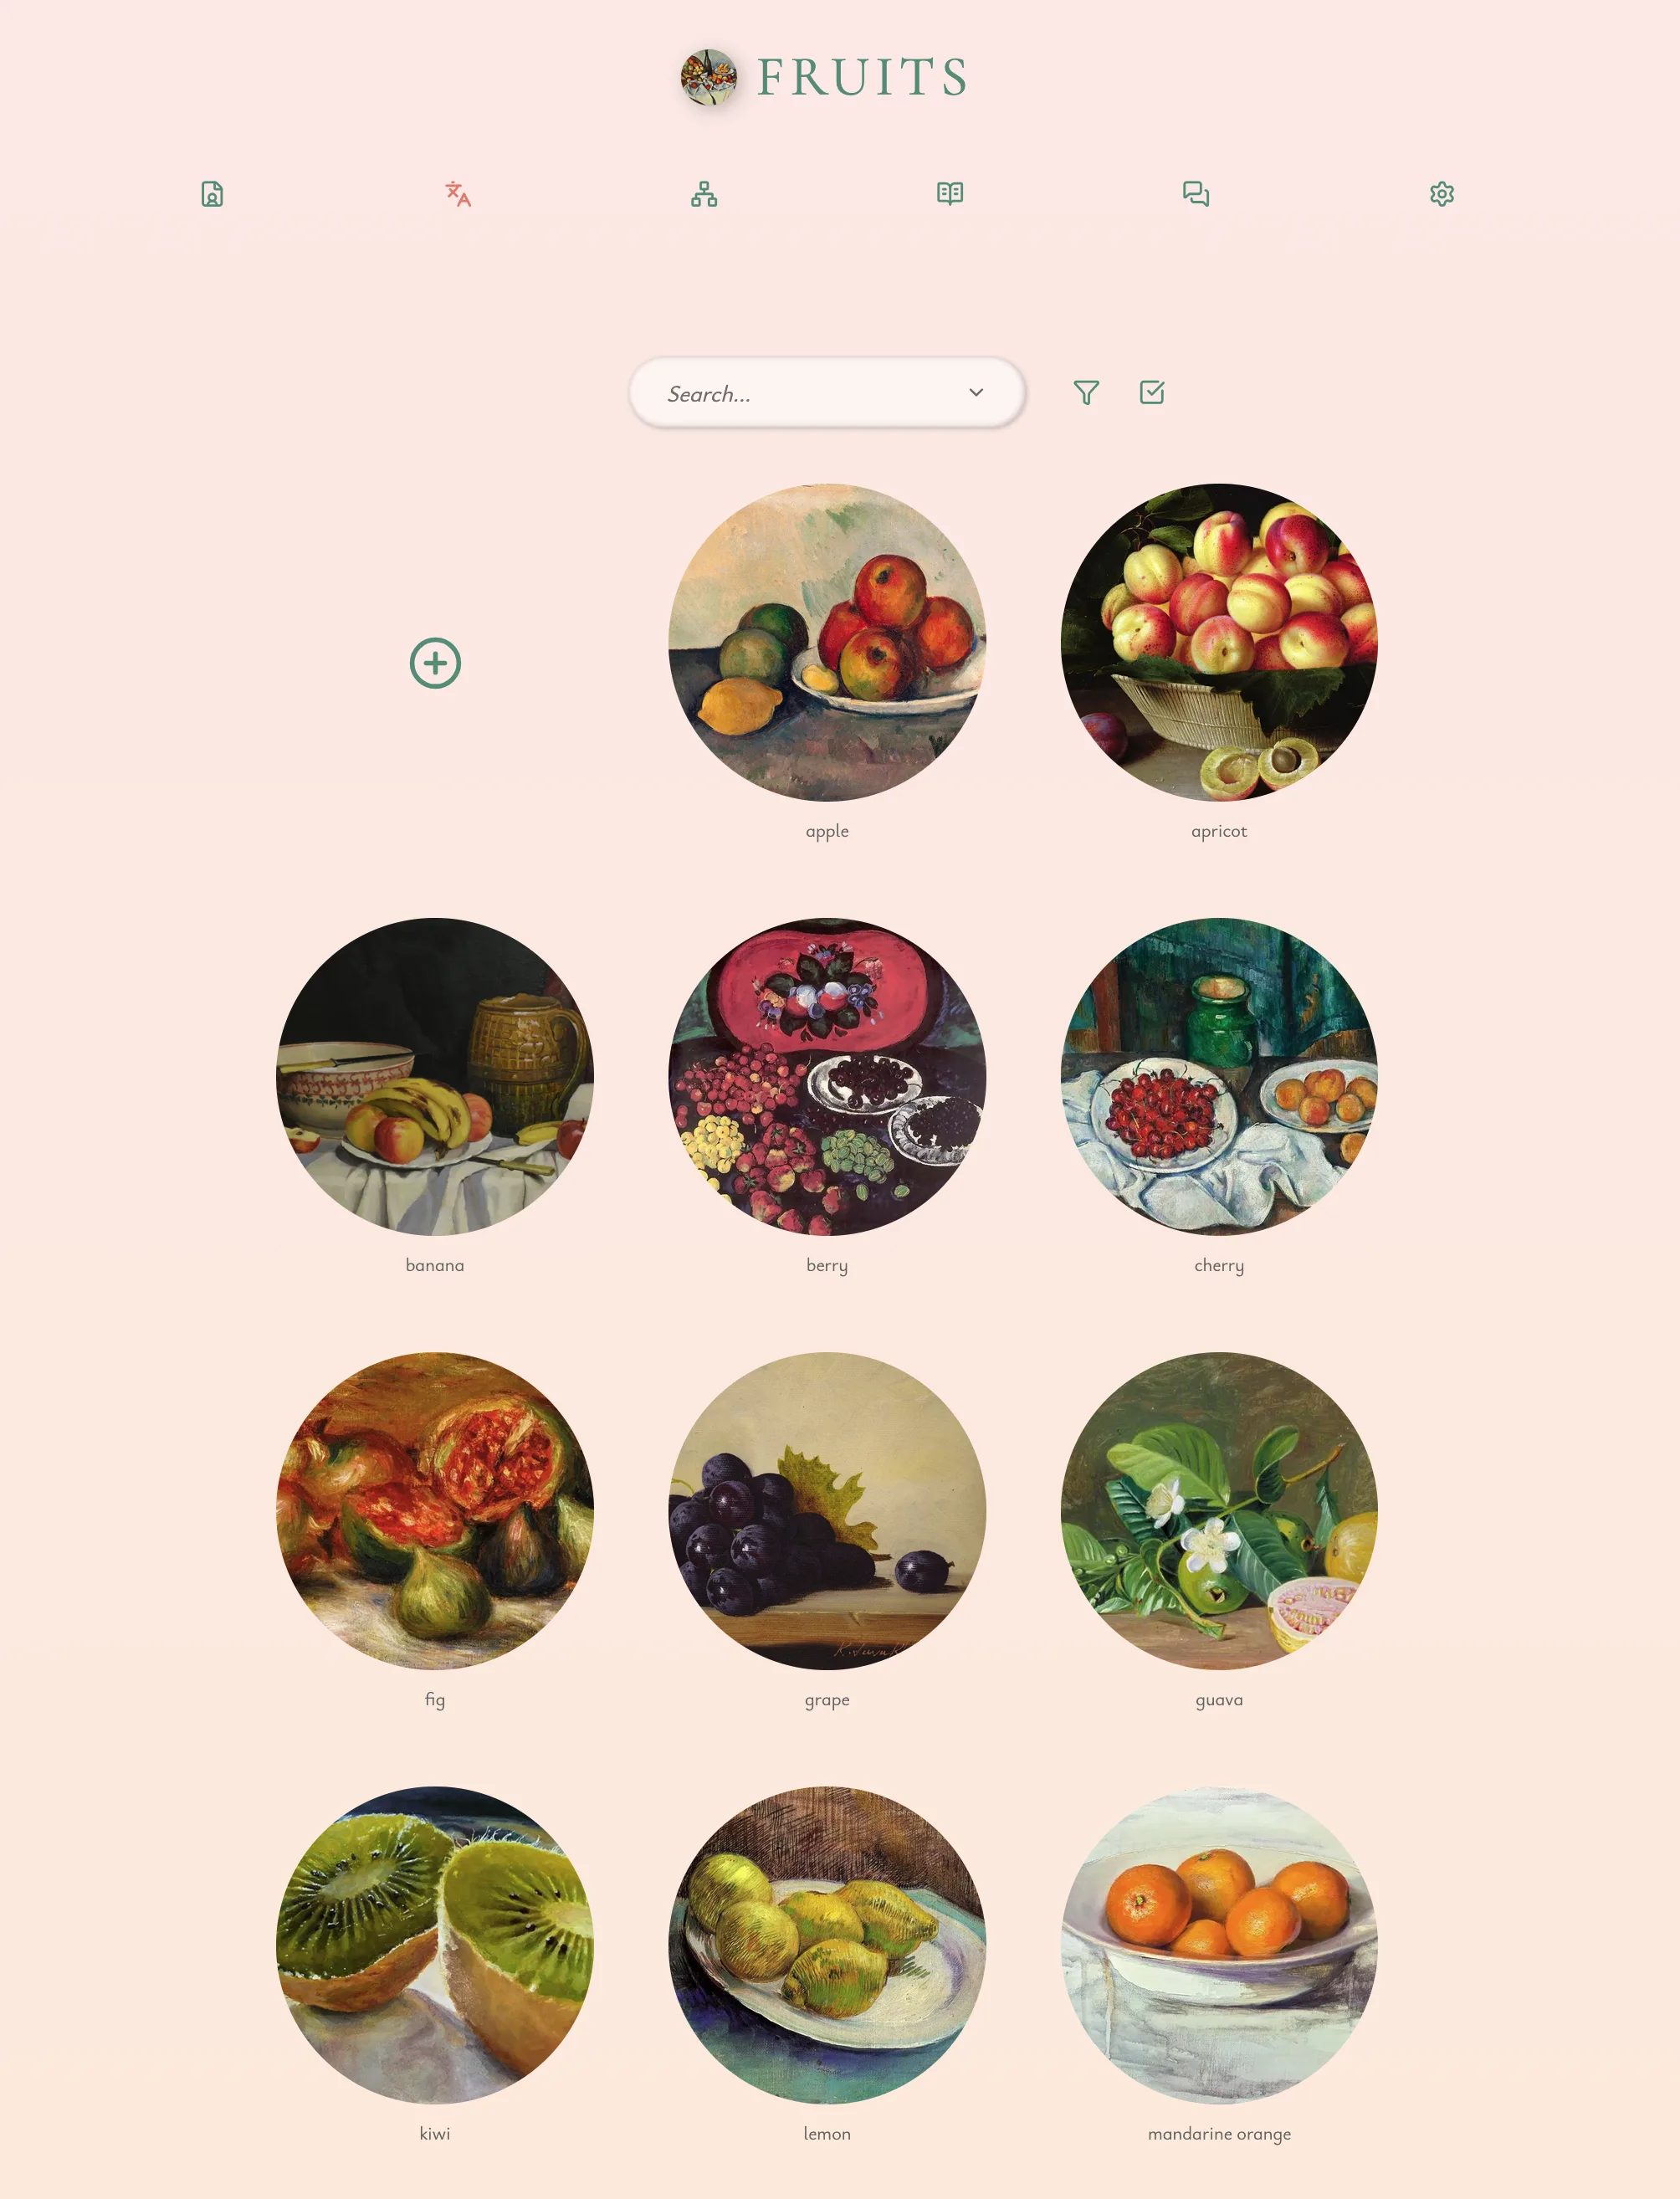
Recorded scope across routes, data models, interface screens, and workflow code.
A multilingual vocabulary platform linking public lessons and protected study workflows to progress tracking, cultural-text ingestion, image generation, and AI-assisted vocabulary pipelines.
Ukrainian vocabulary study spans collections, nested lists, words, translations, grammar references, images, quizzes, progress, goals, and reading lessons. The same records also support generation jobs and review workflows, while learner-facing pages remain focused on study.
Songs and poems yield candidate vocabulary records that can be reviewed before appearing in lists, quizzes, grammar references, and reading lessons.
Landing, about, grammar case, and preview routes introduce structured language learning content.
Protected collections, lists, words, quizzes, progress, goals, calendars, and kids reading pages.
Admin and tool routes manage collection generation, song import, lyric and poem processing, image regeneration, review, reconciliation, and deduplication.
Graph-based pipelines crawl carols and poems, extract dictionary-form vocabulary, translate, reconcile existing words, queue imagery, and persist collections; one carol run processed 19 songs.
Artifacts, gates, telemetry, reconciliation.
R2-backed image workflows.
Implementation details from the product, data, workflow, and infrastructure layers.
Vocabulary is modelled through collections, lists, words, translations, documents, and membership tables.
Learning state includes quizzes, statuses, study plans, goals, and calendar data.
Song pipelines crawl carol sources, preserve lyrics and metadata, and turn each song into a bilingual vocabulary list.
Lyric and poem pipelines chunk longer texts, extract learner-facing vocabulary, standardize entries into dictionary forms, deduplicate candidates, and reconcile against existing words.
One Christmas carol run processed 19 songs and 1,612 source words; a poem-length run consolidated 328 raw vocabulary candidates into 288 unique entries before persistence.
Image-generation workflows create consistent vocabulary imagery, upload assets, and attach generated documents back to accepted word records.
Artifacts, schemas, review gates, reconciliation, image queues, and persistence steps control how AI-generated content enters the product.
Cloudflare deployment uses Workers, D1, R2, and OpenNext-oriented application structure.
Learner-facing routes and internal tools stay separated while sharing the same vocabulary, image, and collection records.
How the public pages, staff workflows, data, review steps, and infrastructure connect.
Landing, grammar, previews.
Collections, lists, words, translations.
Quizzes, progress, goals, kids reading.
Admin, import, generation, deduplication, review.
Crawling, extraction, image queues, persistence.
Technology
Languages, frameworks, data stores, and infrastructure.
A tactile Ukrainian study system: literary typography, floral framing, pale peach fields, sage and coral accents, circular word imagery, and denser review tools for content operations.
Philosophy
The public learning pages stay warm and tactile while the same content model supports protected progress, review queues, image generation, and pipeline persistence.
More screens showing the product in use.